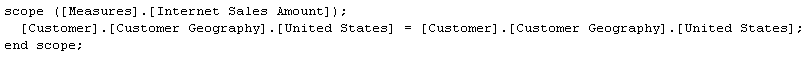Tuesday, November 15, 2011

Avoid Pitfalls of Fact Data Prefetching

As mentioned in Chris Webb’s article Query Performance Tuning in Microsoft Analysis Services and SQL Server CAT team’s white paper SQLServer Best Practices Article: Identifying and Resolving MDX Query PerformanceBottlenecks in SQL Server 2005 Analysis Services, MDX Formula Engine (FE) may request more data from the Storage Engine (SE) upfront so that following SE queries can be answered directly from the SE cache. In order to retrieve the right amount of data, FE uses some clever heuristics to construct the prefetch query. While the underlying design delivers great performance most of the time, sometimes the resulting query prefetches too much data. In this blog post I am going to show you a pathological case where a prefetch query seems to completely ignore the slices in the original MDX query thereby scan all partitions instead of just the needed ones. I will explain why it happens so you understand what’s going on in the engine if you ever run into such cases and deal with it accordingly.

To illustrate the problem, I am going to run a series of MDX queries against the AdventureWorks sample database for Microsoft SQL Server 2008R2. In between queries, I send ClearCache commands to eliminate inter-query interference. For each MDX query, we are going to observe the sequence of SE queries through the Query Subcube Verbose profiler trace events. Instead of showing the complete output of Query Subcube Verbose events, I am going to extract only those attributes in the [Date] dimension which are relevant to our discussion. As well known in the MDX community, Analysis Services engine internally uses subcubes to represent queries, therefore I will use the terms query and subcube interchangeably throughout the post.
Now, let’s run our first MDX query to retrieve the values of measure [Internet Sales Amount] for all days in January 2007.
Query 1:
// January 2007
select [Internet Sales Amount] on 0,
head(descendants([Date].[Calendar].[Calendar Year].&[2007], [Date].[Calendar].[Date]), 31) on 1
from [Adventure Works]

Since measure [Internet Sales Amount] is defined as a measure expression, there are three Query Subcube Verbose events, one for the [Exchange Rates] measure group, two for the [Internet Sales] measure group, although only one of them hits the partitions, the other is just an artifact of measure expression evaluation.

Here are the attributes corresponding to levels in the [Calendar] hierarchy extracted from the trace events:
Dimension 7 [Date] (0 * 8 0 6 0 0 0 0 0 0 20 4 0 0 0 0 0 0 0 0)
[Date]:*
[Calendar Quarter]:[Q1 CY 2007]
[Calendar Semester]:[H1 CY 2007]
[Month Name]:[January 2007]
[Calendar Year]:[CY 2007]

The SE query asks for all days in January 2007, which match exactly the days listed on Axis 1 of the MDX query, with the added benefit of not listing each day individually. There is no prefetch query in this case which makes sense as the original query is asking for all days in January 2007 that matches exactly the SE query.
Now let’s add one more day to the query.
Query 2:

// January 2007 + February 1 2007
select [Internet Sales Amount] on 0,
head(descendants([Date].[Calendar].[Calendar Year].&[2007], [Date].[Calendar].[Date]), 32) on 1
from [Adventure Works]

From the captured profiler trace below

  
You can extract the following information form the three queries sent to the [Internet Sales] measure group:

Non-cache data
Dimension 7 [Date] (0 * 8 0 6 0 0 0 0 0 0 20 4 0 0 0 0 0 0 0 0)
[Date]:*
[Calendar Quarter]:[Q1 CY 2007]
[Calendar Semester]:[H1 CY 2007]
[Month Name]:[January 2007]
[Calendar Year]:[CY 2007]

Non-cache data
Dimension 7 [Date] (0 * 8 0 6 0 0 0 0 0 0 21 4 0 0 0 0 0 0 0 0)
[Date]:*
[Calendar Quarter]:[Q1 CY 2007]
[Calendar Semester]:[H1 CY 2007]
[Month Name]:[February 2007]
[Calendar Year]:[CY 2007]

Cache data
Dimension 7 [Date] (0 582 8 0 6 0 0 0 0 0 0 21 4 0 0 0 0 0 0 0 0)
[Date]:[February 1, 2007]
[Calendar Quarter]:[Q1 CY 2007]
[Calendar Semester]:[H1 CY 2007]
[Month Name]:[February 2007]
[Calendar Year]:[CY 2007]

Again there is no prefetch query for January 2007 but FE does prefetch all days in February 2007 first before getting the value of February 1, 2007 from cached data.
Now let’s add one more day again to the query.
Query 3:
// January 2007 + February 1 2007 + February 2 2007
select [Internet Sales Amount] on 0,
head(descendants([Date].[Calendar].[Calendar Year].&[2007], [Date].[Calendar].[Date]), 33) on 1
from [Adventure Works]

Below is the profiler trace events and relevant information extracted from them:

Non-cache data:
Dimension 7 [Date] (0 * * 0 * 0 0 0 0 0 0 * * 0 0 0 0 0 0 0 0)
[Date]:*
[Calendar Quarter]:*
[Calendar Semester]:*
[Month Name]:*
[Calendar Year]:*

Cache data:
Dimension 7 [Date] (0 * 8 0 6 0 0 0 0 0 0 20 4 0 0 0 0 0 0 0 0)
[Date]:*
[Calendar Quarter]:[Q1 CY 2007]
[Calendar Semester]:[H1 CY 2007]
[Month Name]:[January 2007]
[Calendar Year]:[CY 2007]

Cache data:
Dimension 7 [Date] (0 + * 0 * 0 0 0 0 0 0 * * 0 0 0 0 0 0 0 0)
[Date]:+
[Calendar Quarter]:*
[Calendar Semester]:*
[Month Name]:*
[Calendar Year]:*

One EventSubclass  = Non-Cache data query prefetches fact data into SE cache which is used to answer the subsequent two SE queries shown as EventSubclass  = Cache data, one for all days in January 2007, the other for the first two days of February 2007. But why did the prefetch query ask for data for all dates? Why did we lose all slices in the [Date] dimension? This is really bad as it would have caused all partitions to be scanned. The answer lies in the imprecise nature of the algorithm used to construct the prefetch subcube.

In order to build the prefetch SE subcube, FE keeps track of all relevant MDX sets in a stack-like data structure called Sonar registry. Later on each MDX set in the Sonar registry is used to build a collection of Sonar subcubes. Perfmon counter MDX\Total Sonar subcubes displays the total number of Sonar subcubes generated inside FE.


By default, the conversion from an MDX set to its collection of Sonar subcubes is not a precise process. The resulting Sonar subcubes will cover the original MDX set but may include additional members on some attributes. The Cache Ratio connection string property controls how a Sonar subcube attribute is expanded to include more members than what the original set contains. The actual algorithm is very complex. I am only going to show here a greatly simplified version that illustrates the main idea of the algorithm.

Algorithm 1: Build Sonar subcubes from an MDX set
Input: an MDX set S, for simplicity, assume S is single-grained

For each hierarchy H in S
Since S is single-grained, let Ls be the level of H where members of S reside
For each level L in H starting from the topmost level down to Ls
Identify all members on L with good coverage of S
A member M has good coverage of S if the ratio of the number of its descendants in S to the number of all its descendants on level Ls is greater than or equal to the Cache Ratio
Add M to the list of slicers on level L
For each level with a nonempty list of slicers
Create a Sonar subcube with granularities on attributes corresponding to the levels of H from the topmost level down to Ls
Apply the list of slicers to the subcube

Output: the collection of generated Sonar subcubes

First, apply Algorithm 1 to the [Calendar] set in Query 1

head(descendants([Date].[Calendar].[Calendar Year].&[2007], [Date].[Calendar].[Date]), 31)

you get the following sequence of slices encoded in internal data IDs and eventually FE finds a single good cover slice on the month level.

Sonar [Calendar] [1 * * * * *] ratio: 31/1188
  Sonar [Calendar] [1 4 * * * *] ratio: 31/365
   Sonar [Calendar] [1 4 6 * * *] ratio: 31/181
    Sonar [Calendar] [1 4 6 8 * *] ratio: 31/90
     Sonar [Calendar] [1 4 6 8 20 *] ratio: 31/31 ß good cover

The resulting Sonar subcube is

Sonar Subcube 1
Calendar Year
Calendar Semester
Calendar Quarter
Month Name
Date
2007
H1 CY 2007
Q1 CY 2007
January 2007
*

Here and in the following I only show the important attributes in the Sonar subcube which correspond to levels of the [Calendar] hierarchy. Next, apply Algorithm 1 to the [Calendar] set in Query 2

head(descendants([Date].[Calendar].[Calendar Year].&[2007], [Date].[Calendar].[Date]), 32)

FE finds two good cover slices, one on the month level and the other on the date level.

Sonar [Calendar] [1 * * * * *] ratio: 32/1188
  Sonar [Calendar] [1 4 * * * *] ratio: 32/365
   Sonar [Calendar] [1 4 6 * * *] ratio: 32/181
    Sonar [Calendar] [1 4 6 8 * *] ratio: 32/90
     Sonar [Calendar] [1 4 6 8 20 *] ratio: 31/31 ß good cover

     Sonar [Calendar] [1 4 6 8 21 *] ratio: 1/28
      Sonar [Calendar] [1 4 6 8 21 582] ratio: 1/1 ß good cover

The two Sonar subcubes created are:

Sonar Subcube 2.1
Calendar Year
Calendar Semester
Calendar Quarter
Month Name
Date
2007
H1 CY 2007
Q1 CY 2007
January 2007
*

Sonar Subcube 2.2
Calendar Year
Calendar Semester
Calendar Quarter
Month Name
Date
2007
H1 CY 2007
Q1 CY 2007
February 2007
February 1, 2007


Finally, apply Algorithm 1 to the [Calendar] set in Query 3

head(descendants([Date].[Calendar].[Calendar Year].&[2007], [Date].[Calendar].[Date]), 33)

FE finds three good cover slices, one on the month level and two on the date level.

Sonar [Calendar] [1 * * * * *] ratio: 33/1188
  Sonar [Calendar] [1 4 * * * *] ratio: 33/365
   Sonar [Calendar] [1 4 6 * * *] ratio: 33/181
    Sonar [Calendar] [1 4 6 8 * *] ratio: 33/90
     Sonar [Calendar] [1 4 6 8 20 *] ratio: 31/31 ß good cover

     Sonar [Calendar] [1 4 6 8 21 *] ratio: 2/28
      Sonar [Calendar] [1 4 6 8 21 582] ratio: 1/1 ß good cover

      Sonar [Calendar] [1 4 6 8 21 583] ratio: 1/1 ß good cover

Again, FE created two Sonar subcubes.

Sonar Subcube 3.1
Calendar Year
Calendar Semester
Calendar Quarter
Month Name
Date
2007
H1 CY 2007
Q1 CY 2007
January 2007
*

Sonar Subcube 3.2
Calendar Year
Calendar Semester
Calendar Quarter
Month Name
Date
*
*
*
*
+

Note that Sonar Subcube 2.2 retains slices on all levels of the [Calendar] hierarchy while Sonar Subcube 3.2 only has a slice on the lowest level of the [Calendar] hierarchy. This is an artifact of the current implementation. When multiple covering members of a hierarchy are added to a Sonar subcube, only a single slice is created at the lowest level of the hierarchy.

FE uses Sonar subcubes in several different places, including constructing a larger evaluation node when FE is executing in cell-by-cell mode. In the simple case where an MDX query can be answered directly from SE, Sonar subcubes are used to construct SE queries.

Algorithm 2: Evaluate cell values
Input: a cell iterator and the current Sonar registry
For each cell C
Find the Sonar subcube S that contains C
Build an evaluation node E for S
Execute E. In the simplest case, create SE subcube SSE from S and send SSE to SE.
Lookup value of C from cached result in E
Output: cell values

Another usage of Sonar subcubes is to build a prefetch subcube from a given SE query subcube. The full algorithm is again very complex with exceptions and special handling of arbitrary shapes or unary operators, etc. Here I include a simplified version to illustrate the essence of the algorithm:

Algorithm 3: Build a prefetch subcube for a query subcube
Input: a SE query subcube Squery and the current Sonar registry
Initialize the prefetch subcube Sprefetch as a clone of Squery,
For each Sonar subcube Ssonar in the Sonar registry
For each attribute Aprefetch in Sprefetch
Find the corresponding attribute Asonar in Ssonar
Skip Asonar if it is not a granularity attribute
If Aprefetch is a granularity attribute
If the slice of Asonar is a superset of the slice of Aprefetch
Copy the slice of Asonar to Aprefetch
Else
If the slice of Asonar includes all members
Make Aprefetch a granularity attribute
Output: Sprefetch if it is different from Squery

In Query 1, Sonar Subcube 1 is equivalent to the SE query subcube therefore no prefetch subcube is needed. In Query 2, the first SE query subcube matches Sonar Subcube 2.1 so again no prefetch subcube is needed. But the second SE query would copy the * from [Date] in Sonar Subcube 2.1 therefore produce a prefetch subcube that fetches all days in February. The * in Sonar Subcube 2.1 really means all days in January 2007 but Algorithm 3 treats each attribute independently and is oblivious to the fact that [Date]:* is cross-filtered by slices on other attributes. But the end result of prefetching all days in February 2007 isn’t too bad.

Prefetch Subcube 1
Calendar Year
Calendar Semester
Calendar Quarter
Month Name
Date
2007
H1 CY 2007
Q1 CY 2007
February 2007
*

But when we come to Query 3, there is a * on each attribute from either Sonar Subcube 3.1 or Sonar Subcube 3.2, we end up with a prefetch subcube that has * on all its attributes.

Prefetch Subcube 2
Calendar Year
Calendar Semester
Calendar Quarter
Month Name
Date
*
*
*
*
*

Nowadays we are seeing more and more implementation of systems with multiple terabytes of data in Analysis Services. The above example of overly aggressive prefetching of fact data is unacceptable in such environments. You can disable prefetching altogether by setting connection string property Disable Prefetch Facts=true or you can play with the Cache Ratio connection string property to influence the Sonar subcubes generated by FE. But either approach is likely to have negative performance impact that would require a lot of testing to confirm their overall benefit against a certain query set. If you can control the types of queries in your deployment, it is better to replace queries that fall into this pitfall with ones that produce good Sonar subcubes in the default settings. Using our example, since we know that there are 90 days in the first quarter and the default Cache Ratio is 0.5, we can simply ask for 45 days instead of 33 days to produce a single good cover at quarter level.

Query 4:

// January 2007 + February 1-14 2007
select [Internet Sales Amount] on 0,
head(descendants([Date].[Calendar].[Calendar Year].&[2007], [Date].[Calendar].[Date]), 45) on 1
from [Adventure Works]


The captured profiler trace confirmed our conjecture as it shows a single SE query to the [Internet Sales] measure group to retrieve all days in the first quarter of 2007.

Dimension 7 [Date] (0 * 8 0 6 0 0 0 0 0 0 * 4 0 0 0 0 0 0 0 0)
[Date]:*
[Calendar Quarter]:[Q1 CY 2007]
[Calendar Semester]:[H1 CY 2007]
[Month Name]:*
[Calendar Year]:[CY 2007]

Saturday, October 22, 2011

Three Strategies of Evaluating the MDX Aggregate Function

In the past two months, the Analysis Services development team was preoccupied with wrapping up SQL Server Denali development. I was racing against time to put finishing touches on some exciting new DAX features that I will write in more details once Denali goes public. It didn’t help that PASS 2011 fell on the same week that developers were allowed to make a final batch of code changes before the checkin bar would be lifted prohibitively high. All the flurry of activity forced me to postpone writing blogs on a couple of topics queued up over the past year. Now that things have quieted down a lot on the Denali front, the development team immediately switched gear to work on the next batch of important features requested by many customers, like supporting DAX queries against multidimensional cubes. Over the next few months before Denali hits the stores, I’ll try to finish up several MDX topics that I had put on the backburner due to Denali crunch time.

Before I get to the main subject of today’s post, I’d like to say a few words on PASS Summit 2011 that happened here at Seattle about a week ago. AS team, and Microsoft at large, always encourages product developers to interact with customers through venues like PASS so that we get a chance to see firsthand how the products we have built impact people’s lives. I was gratified to see that Kasper received a round of applause when he gave the audience a glimpse of DAX query plans, a feature I personally fought very hard to be included in Denali. Obviously the room was filled with MDX users who have waited for years an MDX query plan feature. One MVP told me that she thinks MDX is a beautiful language. That was the first time I heard the word beautiful to be associated with MDX, what I had previoulsy heard were all in line with hard or difficult. I have also heard touching stories about how brothers both turned into MDX experts and that a mother passed her MDX knowledge to her daughter.  Who could have thought that MDX can promote family bonding? I could use stories like this to lift my spirit after finishing another grueling product release cycle at Microsoft.
Without further delay, let’s jump into the MDX Aggregate function which is the focus of this post. Many users think of Aggregate as a smart function that dynamically chooses an aggregation type based on the current measure. But this way of thinking only works when the current measure is a physical measure that has an additive aggregation type like Sum, Min, Max, or Count. What should MDX formula engine do when the current measure is a calculated measure which doesn’t have a default aggregation type? Often times the formula engine simply gives up and returns an error, as seen in this blog. Even when the formula engine is able to pick a calculation strategy, it often has limitations that may surprise you when you move beyond basic scenarios. In this blog post I’ll describe three execution plans the formula engine uses to evaluate the Aggregate function and the decision logic employed to pick the winning strategy. The information provided here is valid as of SQL Server 2008R2.
Here are the three possible execution plans for calculating the value V of
Aggregate(«Set»[, «Numeric Expression»])
in the context of the current cell Cwhose subspace is S0

1.      The basic plan.
Many people think of Aggregate as a generic form of Sum, Min, Max, or Count with a similar execution strategy.
Let Agg be the aggregation function derived from the current measure in S0
Set V = NULL
For each tuple t in «Set»
Apply t to S0 to build a new subspace S1
If «Numeric Expression» is present
Set V = Agg(V, value of «Numeric Expression» in S1)
Else
Set V = Agg(V, value property of S1)

The formula engine chooses this strategy when the current measure in S0 is a basic physical measure or is an alias to a basic physical measure, as shown below.

2.      The switching-solve-order plan.
The basic plan stops working when the current measure is a non-trivial calculated measure since the formula engine cannot extract the Agg function any more. One way to work around the problem is to switch the solving order of the AGGREGATE function and the calculated measure. Mosha alluded to this strategy in his comment to Thomas Ivarsson’s post.

Let «Measure Expression» be the expression of the current measure in S0
Set V = Calculate the value of «Measure Expression» in S0

The thinking behind this strategy is that by evaluating «Measure Expression» first, it will eventually lead to a physical measure that has a good Agg function. Afterwards, the Aggregate calculation can be evaluated using the basic plan. This strategy essentially moves an otherwise higher-priority Aggregate calculation behind lower priority calculated measures.
For example, when I slightly change the expression for calculated measure [x] to be more than just a physical measure name, the formula engine would switch the solving orders of [x] and [y] to produce the same result as in the basic plan.


But this strategy falls apart when the calculated measure is more than just a single expression.
If you create [x] and [y] in the cube script in the following fashion,
CREATE MEMBER CURRENTCUBE.Measures.[x] AS NULL;
Measures.[x] = [Measures].[Internet Sales Amount];
CREATE MEMBER CURRENTCUBE.[Date].[Calendar Year].[y] AS NULL;
[Date].[Calendar Year].[y] =
AGGREGATE({[Date].[Calendar Year].&[2007], [Date].[Calendar Year].&[2008]});

you will get the following surprising query result.
This is because the formula engine can only retrieve the original expression of the calculated measure but is unable to take into account scope assignments which also affect the value of the calculated measure. In my opinion, this strategy is more or less a hack as it doesn’t provide a coherent solution under all circumstances.
3.      The set-in-the-where-clause plan.
Neither of the above strategies works when the current measure is a physical measure with a non-additive function, such as semi-additive measures or distinct count measures. To make the function return meaningful result, we borrowed a page from another hacky feature of MDX: multi-select through query-scope calculated member using Aggregate function. The formula engine rewrites the incoming multi-select query into an equivalent query by putting the set argument extracted from the Aggregate function into the where clause.

As it turned out, the same strategy can be used as a generic solution for evaluating the Aggregate function. In 2008R2, this is used for non-additive physical measures.
Construct a new subspace S1 by adding «Set» as a slice to S0
If «Numeric Expression» is present
Set V = Calculate the value of «Numeric Expression» in S1
Else
Set V = Calculate the value property of S1

If you are familiar with DAX, this strategy is similar to the Calculate function in DAX: it transforms the current subspace by applying the set argument as a filter and then evaluates the «Numeric Expression» in the new subspace.
Conclusion
As you can see from today’s discussion, current implementation of the Aggregate function in the face of a calculated measure has limitations and inconsistencies. It may cause confusions among users who saw that basic scenarios worked and then ventured into more advanced usages. Therefore we are considering to give users an option to switch to the set-in-the-where-clause plan where currently the switching-solve-order plan is used.

Wednesday, August 17, 2011

Interaction between MDX Subselect and Calculation

As Mosha Pasumansky has described in his blog AS2008MDX: subselects and CREATE SUBCUBE in non-visual mode, an MDX subselect performs two functions:

  1. Limits each axis set through dimension autoexists.
  2. Applies visualtotals to cell values if there are no coordinate overwrites.

The second point deserves more elaboration especially when there are MDX calculations involved. In this blog post, I will explain how subselect visualtotals works in MDX formula engine and how the presence of MDX calculations can disable visualtotals by overwriting subselect attributes. Let’s start by looking at a series of questions recently raised by an AS customer. Since the original questions were based on customer’s database, I have adapted them to using AdventureWorks.
1. A customer puzzle

First run the following MDX query to find out the original values of USA, CA, and WA.

                                              
Since the value of CA is $5,714,257.69, if we query USA while subselecting by CA, the visual totaled value of USA is $5,714,257.69 as well.

Case 1
Now if you insert a seemingly innocuous calculation into the cube script that simply says USA = USA,

the value of USA suddenly goes back to its original value.

Case 2
What the user really wanted was to define a calculation that calculates USA as the sum of CA and WA.


But he was not able to get visualtotals when he subselected CA. The value of USA is the sum of the values of CA and WA instead of just the value of CA.

Case 3
The user further experimented by assigning a constant value to WA. When he put the WA assignment before the USA assignment,


USA value was still the sum of the values of CA and WA.


Case 4
When the user moved the WA assignment after the USA assignment,


he suddenly got visualtotals on USA!

The above results confused quite a few MDX users.

2. How does subselect visualtotals work anyway?

2.1. Subselect filters without calculation

You can rest assured that there is a consistent logic underneath the above perplexing results. Before we study the interaction between subselect and calculation, let’s first go back to the basics to see how subselect visualtotals is attained when there is no calculation at all.

I’ll start with a quick review of some fundamentals of the formula engine. Every MDX query is split into one or more single-granularity queries. A single-granularity query is represented by a cube subspace, also known as subcube. The formula engine constructs evaluation nodes from those single-granularity subspaces. For every evaluation node, the formula engine determines which calculations apply to its subspace and generates a list of calculation items, one for each applicable calculation. In the future, you will see that calculation item is also called evaluation node item. But I will stick with calculation item in this post. Every calculation is associated with a subspace at the granularities where the calculation is defined. For example, the left side of the trivial assignment USA = USA defines a subspace with granularity at Country level. The formula engine then constructs a subspace for each calculation item by combining the evaluation node subspace with the calculation subspace. The process of constructing an item subspace is too complex to be covered here, but the resulting subspace is always at or below the granularities of the evaluation node subspace. That’s because a calculation simply doesn’t apply to an evaluation node if the subspace of the former is not strictly at or below the granularities of the subspace of the latter. For example, an assignment at the Country level does not affect a query at the City level. The diagram below illustrates an evaluation node and its calculation items.

In the simplest case when there is no calculation like calculated member, scope assignment, unary operator, etc., the formula engine creates a single, special calculation item, called DetailData, which fetches data from the storage engine. You can imagine that the subspace associated with any DetailData calculation item is always at the lowest granularities for the measures to be fetched. Any subselect filters are then used to filter out unwanted members from the DetailData subspace. Afterwards, when the formula engine aggregates measure values from the DetailData subspace into the evaluation node subspace, you get visualtotals since data has been filtered at the lowest level. In practice, the formula engine does not construct DetailData subspace at the lowest granularities since the storage engine can do more than just retrieving and filtering data at leaf levels, it can also aggregate physical measure values at higher granularities. So the DetailData subcubes sent to the storage engine, as shown in SQL Profiler’s Query Subcube trace events, are typically at higher granularities but include any subselect filters as subcube slices which will filter data at leaf levels.

2.2. Subselect filters with calculations.

As we just said, when there is no applicable calculation, visualtotals is achieved by applying filters to the DetailData subspace and then aggregating measure values into a higher granularity subspace. The same logic extends naturally to cases when calculations come into the picture. Unlike DetailData items, the subspace of an arbitrary calculation is not necessarily at the lowest granularities any more. When building the subspace of the calculation item for a calculation, the formula engine examines each subselect attribute one by one, applies a subselect filter only if the attribute is at or above the granularities of the subspace. So if a subspace is at quarter level, subselect filters at quarter or year levels will be applied to the subspace but subselect filters at month or day levels are skipped. The diagram below illustrates how a subselect partially filters a subspace.


In practice, every time the formula engine constructs a new subspace, be it for an evaluation node or a calculation item, it always applies the subset of subselect filters which are at or above the granularities of the new subspace.

2.3. Attributes overwritten by calculations

An MDX calculation is not only defined by the subspace to which it applies, but also by its MDX expression. When the formula engine evaluates an MDX expression, it often transforms one subspace into another by overwriting some of the attributes. For example, MDX tuple expression ([Retailer Sales Amount], [Date].[Fiscal Year].[FY 2011]) changes one subspace to another by overwriting the [Measures] attribute and the [Fiscal Year] attribute and its related attributes. More complex MDX calculation expressions are parsed into formula trees. Subexpressions within a formula tree like tuple expressions or set expressions overwrite attributes in the original subspace to produce new subspaces.

While the formula engine navigates from one subspace to another, through evaluation nodes and calculation items, it keeps track of all attributes that have been overwritten by calculation expressions so far. When it is time to apply subselect filters to a newly constructed subspace, the formula engine skips all overwritten attributes. This rule sometimes leads to unintuitive results, like the ones we saw earlier in section 1. In case 1, the dummy calculation USA = USA overwrites attributes in the [Customer Geography] hierarchy, later on the DetailData subspace is no longer filtered by the California slice on the [State-Province] attribute, the final value for USA ends up being the sum of values of all states.

The rationale behind this rule is that if a user defines a simple calculated measure like ([Internet Sales Amount], [Fiscal Year].[FY 2009]), they really want to see the sales in 2009 when they add this measure to a report even though the report may have a filter on fiscal years 2010 and 2011. If the formula engine had applied the subselect filter after the calculated measure has changed the subspace to fiscal year 2009, user would have got empty result back since the intersection between {2009} and {2010, 2011} yields empty slice on the [Fiscal Year] attribute.
2.4. Answers to puzzle questions

Since calculation USA = CA + WA in case 2 and case 3 overwrites attributes in the [Customer Geography] hierarchy as well, the same rule kicks in to prevent the subselect filter on [State-Province] from being applied, hence no visualtotals for USA. The diagram below illustrates that in cases 1 through 3, overwritten attributes prevents subselect visualtotals.

But what about case 4 when WA = 1000000 is moved after USA = CA + WA? Why did we get visualtotals in that case? This is actually nothing more than a trick question to test how well you know solving orders in MDX. Now that calculation WA = 1000000 has a higher calculation pass value than calculation USA = CA + WA, the latter calculation is not used at all. The diagram below shows that since calculation does not overwrite any attributes, subselect filters still apply.

2.5. Caveats

Note that the rule discussed in 2.3 only applies to subselect visualtotals. MDX VisualTotals function is not affected by overwritten attributes in the same way. The discrepancy between the two styles of visualtotals is due to historical reasons where VisualTotals function had to maintain backward compatibility with SQL Server 2000 behavior.

Also note that the current implementation has complications when an MDX query mixes subselect with set in the where clause. So it’s generally not a good idea to use both features together in the same query.

3. What if a subselect is arbitrarily shaped?

So far we have been applying subselect filters one attribute at a time. We have learned that for a given subspace, some subselect filters can be applied if they are at or above granularity and not overwritten, others cannot be applied if they are below granularity or have been overwritten. This is not an issue when each subselect attribute can be applied independently. What if there is a correlation between two subselect attributes? In AS jargon, what if a subselect is arbitrarily shaped but only a subset of the attributes can be applied to a subspace? In this case, the formula engine projects the subselect onto the applicable filter attributes and then restricts the subspace with the projected set. But if a partial projection is caused by some of the filter attributes overwritten by calculations, the formula engine raises an error instead. For example, insert a dummy calculation WA = WA into the cube script that overwrites the [State-Province] attribute. Issue a query Select USA From (Select {(CA, 2009), (WA, 2008)} From AW) which contains an arbitrary shape subselect and you will get the error Expression cannot be resolved in the context of an arbitrary shape. That’s because the [Fiscal Year] attribute of the arbitrary shape set applies to the subspace but the [State-Province] attribute of the arbitrary shape set does not apply as it has been overwritten by the dummy calculation.

4. Summary

Today we have learned how MDX formula engine implements subselect visualtotals. In general, subselect filters newly constructed subspaces for attributes at or above granularities. The DetailData calculation item can be thought of as working at the leaf levels therefore all subselect filters apply. Other calculation items may work at higher levels hence only a subset of subselect filters are used to restrict their subspaces. Attributes overwritten by calculations are not filtered by subselect.