Monday, June 27, 2011

Under the Covers: MDX IF Statement

It is a well-known best practice in the MDX community to avoid run-time checks by choosing SCOPE over IIF function, and for the same reason, the IF statement. But what is the actual performance impact when you have no choice but to use IIF function or IF statement? I have described in details the block mode algorithm for IIF function in one of my previous blog posts. The other day, Teo Lachev asked whether he needed to worry about performance if he used IF statement in his cube script. In particular, Teo wanted to know if there was any performance impact on other calculations which kick in when the condition of IF statement is false. In my post about IIF function, I mentioned that IF statement is internally rewritten as IIF function calls. Today I am going to add a bit more details on how the rewriting is done and what limitations can prevent the rewriting from happening. What is described here applies equally to the CONDITION clause in a CREATE CELL CALCULATION statement since there is no internal difference between the two MDX features.  

Rewrite to IIF function calls
Let’s consider a simple case where two calculations apply to the same subspace S0, as shown in Figure 1. The calculation, Calc1, wrapped in IF statement has higher priority over the other calculation, Calc2. For example, Calc1 may be at a higher calculation pass than Calc2. When comparing two scope specifications, MDX calculation engine does not take into account conditions of IF statements although they appear to be part of the scope definitions. Instead, conditions in IF statements are evaluated at run-time.

In case you wonder why Calc1 and Calc2 have their own subspaces S1 and S2 even though the evaluation node already has a subspace S0, that’s because the scope of a calculation can be at lower granularity than the subspace of an evaluation node. For example, a query may ask for results at the year level, but there is a calculation at month level. In this case, the calculation is needed to answer the query but the subspace for the evaluation node, which is the same as the subspace of the query, and the subspace of the calculation will be at different granularities.

Figure 2 shows how the IF statement is translated to IIF function calls which are evaluated at run-time. DisjointTest is an internal function that takes as input a given cell and returns true if the cell is not covered by one of the higher priority calculations. In our example, when S1 and S2 are at the same granularity, DisjointTest degenerates into NOT Condition, which returns true when the condition of IF statement returns false. When S2 has lower granularity than S1, DisjointTest first finds a cell in S1 that covers the given cell in S2 and then evaluates NOT Condition in the context of the covering cell.

So unlike IIF(Condition, Calc1, Calc2), where the Condition is evaluated in one subspace, the condition of IF statement is replicated and evaluated in all subspaces of lower priority calculations which apply to the given evaluation node. Consequently, the condition of IF statement will be evaluated in many more cells than the original subspace, especially when the subspaces of lower priority calculations are at lower granularities.

Exceptions
The internal rewriting to IIF does not happen in S2 when Calc2 is a semi-additive measure, a unary operator, or a storage engine query. In those cases, Calc2 is evaluated in a larger subspace not constrained by the opposite condition of the IF statement. This is typically not a problem when Calc2 is to simply fetch data from the storage engine except for really large cubes when fetching the extra data requires a lot of disk IOs. In the other two cases, S2 becomes inexact since now Calc2 is evaluated in more cells than it should. An inexact subspace increases the chance of the MDX calculation engine choosing cell-by-cell mode when it builds the calculation subtree starting from S2.

Tuesday, May 31, 2011

Performance Considerations for Recursive Calculations in MDX (Part 2)

Last time I discussed MDX engine limitations in dealing with recursive calculations. Today I want to describe two more situations where users may run into bad performance when writing recursive calculations in MDX.

Pseudo Infinite Recursion

Last time I recommended users to avoid subspace overlap over the changing attribute of the recursion, in most cases, an attribute in the Date/Time dimension. That’s because MDX calculation engine may choose a cell-by-cell execution plan when it detects sideways recursion. But performance can get a lot worse than simply executing in cell-by-cell mode if MDX calculation engine falsely reports an infinite recursion even though it is actually a sideways recursion. When a calculation applies to two subspaces on the callstack, MDX calculation engine checks for potential infinite recursion. When the two subspaces have overlapping regions, MDX calculation engine checks to see if any cell in one subspace is mapped to itself in the other subspace. This requires MDX calculation engine to keep track of how each MDX expression on the callstack transforms one subspace into another. While there are extensive logic inside MDX formula engine to analyze most common MDX expressions, there are still some MDX expressions which are treated as a black box by the formula engine. Moreover, if one of the subspaces on the callstack is a single-cell subspace, MDX calculation engine switches to lazy execution mode for that expression, and treats the calculation in that subspace as opaque as well. During infinite recursion detection, an opaque calculation on the callstack would force MDX calculation engine to assume the worst and to raise an infinite recursion error even though it is not true.


Error handling is one of the most expensive operations in MDX calculation unless the error simply aborts the entire query. This is especially true in block mode. MDX calculation engine is not sure whether the error happens in one of the cells in the subspace or the error applies to the entire subspace. As a result, parent evaluation node which intercepts the error will abandon all intermediate results and start all over by falling back to cell-by-cell mode and recalculating cell values one by one. For the same reason, if an infinite recursion error is raised due to overlapping region and opaque MDX expression anywhere on the callstack, error handling logic at upper level would force a recomputation of cell values one at a time. This is helpful since if the infinite recursion is not real, it won’t happen again as soon as the changing attribute is reduced to a single member. However, the unwinding process happens one level at a time. If the recursion loop is long, recomputations of cell values at all intermediate levels are wasted effort, see Figure 2.


The false infinite recursion error is repeatedly raised until the beginning of the recursion loop is reached. Only when MDX calculation engine splits the subspace at the beginning of the recursion into individual cells will the false infinite recursion error stops being raised, as by now the beginning subspace would have a single member on the changing attribute and the ending subspace would have a different member on that attribute. To make matters worse, MDX calculation engine has a preference for block mode. Even though a parent level is forced into cell-by-cell mode to avoid false infinite recursion, a child level may still make the same mistake if somehow the subspace is enlarged by some calculation to include more members on the changing attribute. If you see a steady increase of performance counter MDX\Total Recomputes along with the creation of large numbers of evaluation nodes of various kinds, your query may have entered such a vicious cycle.


Impact on Calculation Caches

Aggressively caching intermediate results is one of the key reasons for MDX execution engine to deliver great query performance. MDX execution engine maintains a complex system of various types of caches for different purposes. When a MDX query requires heavy calculation, caches for evaluation nodes tend to play a decisive role in good query performance. An evaluation node is a subspace along with query plans built for all applicable calculations plus, optionally, data caches holding the calculation results. Unlike cached results of storage engine queries which correspond to leaf nodes in an MDX evaluation tree, formula engine evaluation nodes can be at much higher level or even be the root node of an evaluation tree. Hitting or missing an evaluation node at high level in the cache will make a dramatic difference in performance for calculation intensive queries.

MDX calculation engine keeps separate caches for cell-by-cell evaluation nodes and for bulk-mode evaluation nodes. In this section I am going to discuss the impact of recursive calculation on bulk-mode evaluation node caches.

The evaluation node cache mentioned above builds hash tables and indexes to facilitate insertions and lookups of cache entries. The hash function used by the hash table calculates hash values based on the group-by attributes of a subspace, plus some other information which is unimportant for the sake of this discussion. The hash table uses linked lists to implement separate chaining for collision resolution. Since every evaluation node ever created is inserted into the cache, the cache becomes crowded very fast. When a linked list becomes too long, evaluation nodes are evicted from the cache, as reflected by the performance counter MDX\Number of evictions of evaluation nodes.

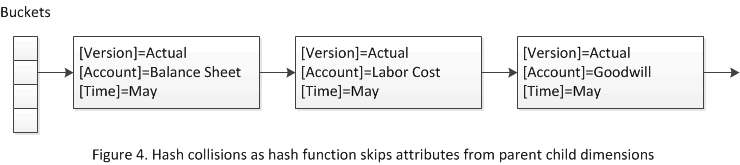
Recursion can easily generate a large number of evaluation nodes. Starting from the original query subspace, the evaluation tree can grow quite big as recursion grows deeper and deeper. This in turn puts heavy pressure on evaluation node caches. To exacerbate the situation, the hash function mentioned previously skips group by attributes in parent child dimensions, as a result, subspaces with a lot of parent child dimensions have a much higher chance of hash collision. On the other hand, recursive calculations tend to show up in financial cubes which usually contain a lot of parent child dimensions. So recursion in a cube with a lot of parent child dimensions has a high chance of eviction of cached evaluation nodes and a low chance of hitting a previously built evaluation node.


You can increase the maximum length of all linked lists by increasing the values of private server configuration properties CalculationLRUMinSize and CalculationLRUMaxSize as the eviction threshold is dynamically calculated but always falls in the interval [CalculationLRUMinSize, CalculationLRUMaxSize]. Increasing the size of the linked lists only allows more evaluation nodes to stay in the cache. You also have to increase the value of private server configuration property CalculationCacheRegistryMaxIterations so that those entries are actually examined during cache lookup.

Summary

In this blog post, we explored two more scenarios in which the presence of recursive MDX calculations can negatively impact query performance. MDX calculation engine may raise false infinite recursion errors when the changing attribute has more than one member in the subspace and when there are a mix of block mode evaluation nodes and cell-by-cell mode evaluation nodes along the recursion path. Although not a definitive diagnosis, you can watch the performance counter Total recomputes to get an indication that unwarranted errors are causing the query slowdown. As recommended in my previous post, keeping a single member on the changing attribute will prevent this issue.

We often find recursive calculations in financial cubes, which also tend to have many parent child dimensions. The combination of the two is cache unfriendly for bulk mode evaluation nodes. Here is one way to help you identify this problem. Assume there is a recursive calculation based on the [Month] attribute. First issue a query to calculate the value in January. After the query finishes, issue a query to calculate the value in February. After that, issue a query to calculate the value in March, so on so forth. If each query comes back fast in this fashion of successive calculations but a query to calculate the value in December is slow when starting in cold cache mode, this is an indication that your recursive calculation can benefit from hitting previously cached results but the large number of evaluation nodes generated by a deep recursion is evicting good cached results. Sometimes increasing the maximum size of hash collision chain of the evaluation node cache may help.

Most of these problems arise because block mode evaluation can be improved in terms of infinite recursion detection and sideways recursion handling. While that may happen in a future release of Analysis Services, a potential workaround is to force a pure cell-by-cell mode for all calculations. SQL Server 2000 performed calculations in cell-by-cell mode only. Many cubes designed back in SQL Server 2000 days worked well enough in that mode with acceptable and predictable query performance. If none of my other recommendations work for you and you suspect that pure cell-by-cell mode may be what you need, you can contact Microsoft Customer Support and Services to explore such a possibility.

Wednesday, April 27, 2011

Performance Considerations for Recursive Calculations in MDX

The other day, while investigating a customer performance problem, Chris Webb came up with a sequence of very simple and targeted MDX queries against SQL Server 2008 Adventure Works database that clearly illustrate some of the pitfalls people may encounter when they write recursive MDX formulas. Today we explore how MDX formula engine generates execution plans for those queries and discuss some engine limitations in this area that may have big impact on query performance.

Chris Webb’s Queries

Chris defined a test measure, [rtest], that recursively counts the number of days from the current date back to 07/01/2001. His first query calculates [rtest] against all customers with a slice on date 07/31/2001. The query finished in about one second to return 118,484 cells.

Query #1

WITH MEMBER MEASURES.rtest AS
  IIF (
    [Date].[Date].CURRENTMEMBER IS [Date].[Date].&[20010701]
    , 1
    , 1 + (MEASURES.rtest, [Date].[Date].CURRENTMEMBER.PREVMEMBER)
  )
SELECT
  MEASURES.rtest ON 0,
  [Customer].[Customer].[Customer].MEMBERS ON 1
FROM [Adventure Works]
WHERE ([Date].[Calendar].[Date].&[20010731])

Next Chris trimmed down the number of customers to be slightly less than 50% of all customers and ran the query again. The query finished a little bit faster than the first one as expected.

Query #2

WITH MEMBER MEASURES.rtest AS
  IIF (
    [Date].[Date].CURRENTMEMBER IS [Date].[Date].&[20010701]
    , 1
    , 1 + (MEASURES.rtest, [Date].[Date].CURRENTMEMBER.PREVMEMBER)
  )
SELECT
  MEASURES.rtest ON 0,
  HEAD ([Customer].[Customer].[Customer].MEMBERS, 9241) ON 1
FROM [Adventure Works]
WHERE ([Date].[Calendar].[Date].&[20010731])

But adding one more customer to the second query suddenly increased query execution time to 20 seconds. The obvious question is what is so significant about querying 50% or more of total customers.

Query #3

WITH MEMBER MEASURES.rtest AS
  IIF (
    [Date].[Date].CURRENTMEMBER IS [Date].[Date].&[20010701]
    , 1
    , 1 + (MEASURES.rtest, [Date].[Date].CURRENTMEMBER.PREVMEMBER)
  )
SELECT
  MEASURES.rtest ON 0,
  HEAD ([Customer].[Customer].[Customer].MEMBERS, 9242) ON 1
FROM [Adventure Works]
WHERE ([Date].[Calendar].[Date].&[20010731])

Chris then tried to remedy the situation by cleverly adding a helper measure, [rtest2], that pre-calculates [rtest] in the range of desired dates in the hope that calculating values of later dates can hit caches of values of earlier dates. I omitted several intermediate queries that led Chris to this idea. When he tried out his idea against the problem query, execution time was cut down to about 12 seconds, an improvement from 20 seconds.

Query #4

WITH MEMBER MEASURES.rtest AS
  IIF (
    [Date].[Date].CURRENTMEMBER IS [Date].[Date].&[20010701]
    , 1
    , 1 + (MEASURES.rtest, [Date].[Date].CURRENTMEMBER.PREVMEMBER)
  )
MEMBER MEASURES.rtest2 AS
  IIF (
    ISEMPTY(
      SUM(
        [Date].[Date].&[20010701] : [Date].[Date].CURRENTMEMBER,
        MEASURES.rtest
      )
    )
    , null
    , MEASURES.rtest
  )
SELECT
  MEASURES.rtest2 ON 0,
  HEAD ([Customer].[Customer].[Customer].MEMBERS, 9242) ON 1
FROM [Adventure Works]
WHERE ([Date].[Calendar].[Date].&[20010731])

But the same trick didn’t help the original query, which now takes about 38 seconds to finish.

Query #5
WITH MEMBER MEASURES.rtest AS
  IIF (
    [Date].[Date].CURRENTMEMBER IS [Date].[Date].&[20010701]
    , 1
    , 1 + (MEASURES.rtest, [Date].[Date].CURRENTMEMBER.PREVMEMBER)
  )
MEMBER MEASURES.rtest2 AS
  IIF (
    ISEMPTY(
      SUM(
        [Date].[Date].&[20010701] : [Date].[Date].CURRENTMEMBER,
        MEASURES.rtest
      )
    )
    , null
    , MEASURES.rtest
  )
SELECT
  MEASURES.rtest2 ON 0,
  [Customer].[Customer].[Customer].MEMBERS ON 1
FROM [Adventure Works]
WHERE ([Date].[Calendar].[Date].&[20010731])

Block Mode vs. Cell-by-Cell Mode

As it turned out, queries #1 and #2 run fast because they execute in block mode. On the other hand, queries #3, #4, and #5 all execute in cell-by-cell mode. But how do I know that? Well, I admit that Analysis Services product team owes the MDX community good diagnostic features, such as MDX query plans, to easily identify such problems. Before such features become available, we have to make do with what we have today, namely PerfMon counters and SQL Profiler trace events. In this case, PerfMon counters can be very revealing. If you start PerfMon and add the counter MSAS 2008:MDX/Total flat cache inserts, rerun queries #2 and #3 with cache cleared, you will see that the counter stays at 0 during query #2 but jumps to 286,502 at the end of query #3. Flat cache is one of the many data caches maintained by MDX formula engine and is used to store single-cell calculation results. The large number of inserts into this cache during query #3 indicates that the query runs in cell-by-cell mode. I'd like to add that cell-by-cell mode can be reflected in other PerfMon counters under a different circumstance. Just because Total flat cache inserts is zero, does not necessarily mean query is in block mode.

Sideways Recursion and Inexact Subspace

Now we know adding one more customer to query #2 tips MDX formula engine over the edge into cell-by-cell mode, but what is so special about the threshold of 50% of members in an attribute set? When MDX formula engine constructs a query subspace, it does not always construct the exact subspace as specified by the MDXMDX formula engine has an easy way to indicate that all customers are included in the subspace. Later operations like determining overlapping regions between two subspaces or detecting whether a cell belongs to a subspace become fast and efficient. But the real benefit of this expansion is to fetch more fact data into detail data cache, so that following queries have a much higher chance of hitting a cache entry. An obvious downside of this expansion is the possibility of fetching too much data. If there are four years of data in the cube and a query selects two years, AS engine ends up retrieving all four years of data. A much more serious problem with this expansion is when there are calculations applicable to the subspace. A single extra member may introduce an unwanted calculation that kills performance. The 50% threshold is arbitrary and is controlled by private server configuration flag QueryOptimizerRatio. Now change the ratio from -1 to 0.7 and rerun query #3, the query finishes instantly. You should know that Microsoft does not support customers who temper with private server configuration settings without authorization from Microsoft Customer Service and Support.

So MDX formula engine expanded the subspace for query #3 to include all customers, the expanded subspace ended up being the same as the one in query #1, but why was query #3 so much slower than query #1? In addition to expanding the subspace in query #3, MDX formula engine also marks the query subspace as inexact for the obvious reason that the subspace contains more customers than requested. Inexact subspaces have several repercussions on building query plans. Loosely speaking, whenever MDX formula engine runs into a potentially expensive operation and when one of the parent subspaces is inexact, it is likely to fall back to cell-by-cell plan as the expensive operation may be unnecessarily introduced by the extra members added.

The next concept to explain is sideways recursion. A recursion happens when the same calculation shows up twice on the stack of current calculations. When the two subspaces to which the calculation is applied have the same granularity and there is no slice change from a regular member to a calculated member or vice visa, the recursion is called sideways recursion. So if one subspace is at All level on an attribute, but the other subspace is at leaf level, the recursion is not a sideways recursion.

When MDX formula engine detects a sideways recursion in the context of an inexact subspace, it chooses a cell-by-cell execution plan. There are a couple of reasons for making such a choice.  In addition to query execution, MDX formula engine is also responsible for detecting infinite recursions. Detecting infinite recursion in block mode is more complicated than in cell-by-cell mode. Even when a calculation shows up twice on the stack of current calculations and the two subspaces to which the calculation is applied have overlapping regions, it does not necessarily entail an infinite recursion. There have been cases where it takes a long time to detect an infinite recursion in block mode and it turns out that time is wasted as the subspace is enlarged through expansion. So currently MDX formula engine resorts to cell-by-cell mode when it encounters sideways recursion and when one of the parent subspaces is inexact. If you want to keep all subspaces exact throughout the execution process to overcome this constraint, you can change another private server configuration property, SpaceDecomposition, from default value of 8 to 9. You can try the new value and rerun query #3 again to see instant result. Why isn’t this default setting? Wouldn’t precise subspaces be a good thing all the time? The Analysis Services product team tried to make the switch during SQL 2008 development but found that precise subspaces hurt performance much more often than helping. Precise subspaces tend to carry a lot of large slices and often arbitrary-shaped slices. Arbitrary-shaped slices are a well-known reason of MDX query performance degradation. More importantly, precise subspaces make it hard to hit caches. Extensive caching of intermediate results is one of the secret recipes of good MDX query and calculation performance.

Recursion and Subspaces Overlapping on Shifted Attributes

Although sound promising in concept, queries #4 and #5 do not perform as well as queries #1 and #2 since they also run in cell-by-cell mode. But the subspace for query #5 is precise, why does it still enter cell-by-cell mode? The execution plan for query #5 enters cell-by-cell mode for a different reason.

Chris introduced the following helper expression

  SUM(
    [Date].[Date].&[20010701] : [Date].[Date].CURRENTMEMBER
    ,MEASURES.rtest
  )

in the hope that MDX calculation engine will calculate [rtest] on 07/01/2001 first, and then each following day will hit the cached result of the previous day. But MDX formula engine always tries to execute in block mode first. So when constructing the subspace for the evaluation of the scalar argument of SUM, the engine adds all dates from the set argument to the subspace. The diagram below shows the important subspaces constructed when executing query #5.


The steps below illustrate the import stages during query #5 evaluation.

Construct subspace 1 from MDX query.
Build query plan for calculation rtest2 in subspace 1.
        Build query plan for sub-expression Sum(07/01/2001 : 07/31/2001, rtest)
        Construct subspace 2 by adding MDX set 07/01/2001 : 07/31/2001 to subspace 1.
        Build query plan for calculation rtest in subspace 2.
                Build query plan for sub-expression (rtest, Date.PrevMember).
                Construct subspace 3 by shifting all dates in subspace 2 to the previous date.
                Build query plan for calculation rtest in subspace 3.
                Detect recursion and overlapping dates. Choose cell-by-cell plan.

When MDX formula engine detects recursion and the two subspaces have overlapping regions, it is potentially an infinite recursion. But the overlapping dates have been shifted, so whether or not there is infinite recursion depends on the MDX operation that performed the shifting. It is obvious in this case there is no infinite recursion. But MDX formula engine has to handle the general case when there are a series of shifting operations between the two subspaces. To play it safe, the engine chooses cell-by-cell execution plan again.

Why is choosing cell-by-cell mode bad for performance in this case? Doesn’t the recursive formula force the engine to evaluate [rtest] one day at a time anyway? That’s true. But there are also 118,484 customers in the subspace. Right now cell-by-cell is a global decision. While going cell-by-cell over days is not a bad thing in this case, going over customers one by one is. Ideally, we want the formula engine to go block on [Customer] attribute, but cell-by-cell on [Date] attribute.

Another downside of choosing cell-by-cell mode in subspace 3 is that the decision will propagate back to all parent calculations as well. MDX formula engine cannot take advantage of sparsity of underlying data when calculation is in cell-by-cell mode. Since building execution plan for [rtest] in subspace 3 is a part of building the overall execution plan for [rtest2] in subspace 1, choosing cell-by-cell plan in subspace 3 ends up forcing a bad plan for [rtest2] in subspace 1 as well.

We don’t have this problem in queries #1 and #2 since there is only a single date in the subspace. When constructing a new subspace, [Date].PrevMember shifts the current date to the previous date. The newly constructed subspace has a different date from all previously constructed subspaces, therefore, there is no risk of infinite recursion. As a result, the execution plan stays in block mode.

Deep Recursion and CLR Assembly

The next topic is unrelated to Chris Webb’s queries but still important for recursions in MDX. Each additional recursive step consumes more space on the stack. A very deep recursion will eventually use up all space on the stack. When that happens, MDX formula engine creates a fiber and switches execution on to the new fiber. But it is not always safe to call managed code from within a fiber since you may get stack overrun problem. In SQL Server 2008 R2, MDX formula engine raises an error when this happens. But the error does not abort the current query to return to user immediately. Most errors cause MDX formula engine to switch to cell-by-cell mode in case some cells contain errors but others don’t. So instead of seeing a query fail quickly, you may end up waiting a long time for it to fail eventually. Note that VBA library is registered as a CLR assembly hosted by Analysis Services, so calling VBA functions in MDX recursion may trigger the fiber exception and cause performance problems. Also note that some VBA functions have been implemented directly in Analysis Services, therefore are safe to use inside recursion. Setting private server configuration flag AllowCLRStoredProcedureCallsInFiberMode to 1 would prevent the exception from being raised.

Conclusions

So far, we have discussed three important performance limitations imposed by MDX formula engine when it encounters recursions. We have learned that to achieve better performance when writing recursive MDX formulas, you should:

  1. Don’t write recursive formulas unless really needed. Non-recursive MDX formulas are not subject to the limitations discussed in this post.
  2. Keep the subspaces precise. Try to stay with queries that produce nice, rectangular-shaped query spaces which don’t trigger the 50% rule. Playing with SpaceDecomposition is an option but you need approval from Microsoft Customer Service and Support to use it in production environment. Note that always enforcing precise subspaces is likely to have an overall negative impact on query performance.
  3. Avoid subspace overlap over shifted attributes. Most recursions happen along the time line. Keeping a single date in the subspace is one way to guarantee that subspaces don’t overlap.
  4. Avoid calling into CLR assembly when recursion is very deep.
As always, performance advices apply to particular versions of a product. The recommendations given in this post apply to all currently supported versions of Analysis Services with the latest one being 2008 R2. The Analysis Services product team will continue to evolve the product and some of the limitations are likely to be lifted in future releases. When you test your recursive calculation, you should start at the beginning and gradually increase recursion depth. Observe whether query time increases at worst linearly as recursion depth increases. Make sure you test the case when the recursion is the deepest as needed by the user.

Monday, March 21, 2011

The Logic behind the Magic of DAX Cross Table Filtering

Automatic cross filtering between columns of the same table or related tables is a very powerful feature of DAX. It allows a measure to evaluate to different values for different cells in a pivot table even though the DAX expression for the measure does not change. Filter context is the underlying mechanism that enables this magic behavior. But it is also a very tricky concept that even befuddles some DAX experts. Marco Russo and Alberto Ferrari have introduced DAX filter context in Chapter 6 of their book Microsoft PowerPivot for Excel 2010. Marco has also blogged about how Calculate function works. Recently I have run into many questions from advanced DAX users which tell me that people are still confused about how filter context works exactly. And this will be the subject of today’s post.
This post assumes that you already have basic knowledge about measures, row context, filter context, and DAX functions Calculate, Values, All, etc.
A level 200 pop quiz on DAX
If you think you already know how filter context works, let me ask you a couple of level 200 questions on DAX to see if you can explain the nuances of some DAX expressions. If you don’t feel like being challenged now, it is still beneficial to read the questions so you have some examples to better understand the following sections. The questions are based on the data model inside the publicly available sample PowerPivot workbook Contoso Samples DAX Formulas.xlsx. You can download the sample workbook to try out the formulas yourself if you want to, but it is not required to answer the questions.
Question #1.
People have heard that fact tables are automatically filtered by slices on dimension tables, but not the other way around, or in more general terms, if there is a relationship from table A to table B, A is automatically filtered by any slices on columns of B but B is not automatically filtered by any slices on columns of A. So if you select
DimProductSubcategory[ProductSubcategoryName] = “Air Conditioners”
on a pivot table slicer, measure
CountRows(DimProduct)
returns 62 as DimProduct is limited to air conditioners. On the other hand, if you select
DimProduct[ProductLabel] = “0101001”,
measure
CountRows(DimProductSubcategory)
returns 44 instead of just 1 although only a single product is selected. To filter DimProductSubcategory by the selected product label, you can define a measure as
Calculate(CountRows(DimProductSubcategory), DimProduct)
which returns 1. So it seems like when you explicitly add DimProduct as a setfilter argument of Calculate, DimProductSubcategory will be filtered by DimProduct. But if I define a measure as
Calculate(CountRows(DimProductSubcategory), Values(DimProduct[ProductLabel]))  
to explicitly add the column that I know having a slice from the pivot table to the Calculate function , the measure formula returns 44 again. So what makes setfilter expression DimProduct work but Values(DimProduct[ProductLabel]) not work even though the filter only comes from [ProductLabel] column? If you think you have to add foreign key DimProduct[ProductSubcategoryKey] to the filter context in order for DimProductSubcategory to be filtered by DimProduct, you can try
Calculate(CountRows(DimProductSubcategory), Values(DimProduct[ProductSubcategoryKey]))
but it still returns 44. If you have enough patience, you can use Values function to explicitly add all 33 columns in DimProduct one by one as setfilter arguments to Calculate function and you still will get 44 back. So what is the difference between table expression DimProduct and the enumeration of all 33 columns in that table?
Question #2.
There are 2556 records in DimDate table, therefore if you add a measure with expression
CountRows(DimDate)
to a pivot table without any filters, the measure value would be 2556. Now if you add a second measure with expression
Calculate(CountRows(DimDate), FactSales)
to the same pivot table, the measure value would be 1096 since DimDate table is filtered by FactSales table and only dates with sales records are included. But if you add a third measure with expression
Calculate(CountRows(DimDate), All(FactSales))
to the pivot table, the measure value becomes 2556 again. Since this pivot table has no filters anywhere, shouldn’t FactSales and All(FactSales) return the same table? Now add a fourth measure with expression
Calculate(CountRows(DimDate), Filter(All(FactSales), true))
to the pivot table, the measure value becomes 1096 again. All three setfilter arguments return exactly the same table, why would we get back different results?
With these questions in mind, let’s examine the logic foundation upon which the magic world of DAX is built. At the end of the post, you will be able to find a logical explanation to all these seemingly inconsistent results.
The expanded view of a DAX base table
The best way to understand DAX cross table filtering is to think of each base table as extended by its related tables. When a relationship is created from table A to table B, the new A, which is really A left outer join B, includes both columns of A and columns of B. So in DAX, a table reference FactSales really refers to
FastSales
LOJ DimProduct LOJ DimProductSubcategory LOJ DimProductCategory
LOJ DimStore LOJ DimGeography LOJ DimDate LOJ DimChannel LOJ DimPromotion,
where LOJ means left outer join. This interpretation makes it easy to understand some other DAX syntax. For example, in DAX expression
Filter(FactSales, Related(DimProduct[ProductLabel])  = “0101001”),
Related(DimProduct[ProductLabel])  refers to the value of column DimProduct[ProductLabel]  in the extended FactSales table. As a second example, DAX expression
AllExcept(FactSales, DimProduct[ProductLabel])
returns a table with all columns of extended FactSales table except for column DimProduct[ProductLabel].


Build initial filter context
DAX filter context is a stack of tables. At the beginning, the stack is empty. Given a pivot table, a filter context is initially populated by adding slicers and page filters. For each cell in a pivot table, current members of row labels and column labels also add filters to filter context. Other pivot table operations like visual totals add to initial filter context as well but I will keep things simple here. At this point, we have set up an initial filter context in which the measure expression of the current cell is to be evaluated.
Measure invocation
If SumOfSales is the name of a measure and Sum(Sales[Amount]) is its DAX formula, DAX expression
[SumOfSales]
is equivalent to
Calculate(Sum(Sales[Amount]))
 and DAX expression
[SumOfSales](Date[Year] = 2001, Store[Country] = “USA”)
is equivalent to
Calculate(Sum(Sales[Amount]), Date[Year] = 2001, Store[Country] = “USA”).
So the syntax sugar which makes a measure name look like a function name is just a clever way to add tables to filter context before evaluating the expression associated with the measure. Since invoking a measure implicitly calls Calculate, from now on I’ll just focus on Calculate function as the same rules apply equally to measures.
Add tables to filter context
Calculate function performs the following operations:
1.       Create a new filter context by cloning the existing one.
2.       Move current rows in the row context to the new filter context one by one and apply blocking semantics against all previous tables.
3.       Evaluate each setfilter argument in the old filter context and then add setfilter tables to the new filter context one by one and apply blocking semantics against all tables that exist in the new filter context before the first setfilter table is added.
4.       Evaluate the first argument in the newly constructed filter context.
If a new table is added to filter context and it has blocking semantics against some tables already in the filter context, the affected tables are checked one by one, all common columns with the new table are marked as blocked on the existing table.
Let’s look at an example. Assume the current filter context has two filters: one filter is Date[Year] = 2011, the other filter is Store[Country] = “Canada”. We want to evaluate the following expression in the context
AverageX(Distinct(Date[Month]), Calculate(Sum(Sales[Amount]), Store[Country] = “USA”)).
The first argument of AverageX sets a month in row context.  When it comes to Calculate, it first removes the month from row context and adds it to filter context, it does not block anything since there is no [Month] column in existing filters. Next Calculate adds Store[Country] = “USA” to filter context which blocks existing filter Store[Country] = “Canada”. When Sum(Sales[Amount]) is evaluated, Sales table is filtered by the current month in 2011 and stores in USA.

Targets of filter context
After so much effort populating and modifying a filter context, when will the filters be applied? In DAX, the filters in a filter context apply to following DAX table expressions:
1.       A table expression that is simply a table reference, such as FactSales.
2.       Values(Table[Column]).
3.       Distinct(Table[Column]).
In cases of 2 and 3, the Table is filtered by filter context and then distinct values of [Column] are extracted from the filtered table.
So if your expression is
Calculate(SumX(Filter(FactSales, [SalesQuantity] > 1000), [SalesAmount]), Date[Year] = 2011),
the filter context only restricts FactSales and has no effect whatsoever on other parts of the formula. If you image every DAX formula is represented as a tree of parent and child function calls, a filter context is built at the top or in the middle of the tree but takes effect at leaf level table nodes.


Note that DAX function Sum(T[C]) is just a shorthand for SumX(T, [C]), the same is true for other aggregation functions which take a single column reference as argument. Therefore the table in those aggregation functions is filtered by filter context.
Apply filters to a target table
Finally we have identified a target table and are ready to apply filters from filter context. For each filter table in the filter context, we check to see if there are any common columns between the target table and the unblocked columns of the filter table. If there is at least one common column, the target table is semi-joined with the filter table, or in SQL-like terms
SELECT *
FROM TargetTable AS t
WHERE EXISTS
(
SELECT *
FROM FilterTable AS f
WHERE t.CommonColumns = f.CommonColumns
)
Each filter table is applied to the target table independently, so the target table is filtered by all relevant filters.
All, AllExcept, AllNoBlankRow
So far I have said that each setfilter argument of Calculate function returns a table which is added to filter context. Well, that is true as long as the setfilter is not one of the All functions. The All functions should really be renamed as BlockColumns when they are used as setfilter arguments. If one of the All functions is used as the top-level function of setfilter, it only blocks common columns of earlier tables but does not add itself to filter context.
In all other places, including as a sub-expression of a setfilter but not at the top level, All functions behave like any other DAX table expressions and always return a table. One special feature of All functions is that the Table argument inside All(Table), All(Table[Column]), AllExcept(Table, …), AllNoBlankRow(Table), etc. is not filtered by the current filter context.
Pop quiz answers
Answer to question #1.
When the initial filter context contains column DimProduct[ProductLabel], table DimProductSubcategory is not filtered as it does not have that column.
Now look at the next formula
Calculate(CountRows(DimProductSubcategory), DimProduct).
The setfilter argument DimProduct is filtered by [ProductLabel], and then table DimProductSubcategory is filtered by table DimProduct since they both share the columns from table DimProductSubcategory and table DimProductCategory.
Move onto the next two formulas
Calculate(CountRows(DimProductSubcategory), Values(DimProduct[ProductLabel]))
Calculate(CountRows(DimProductSubcategory), Values(DimProduct[ProductSubcategoryKey]))
Both setfilter arguments are a single column table and the column comes from table DimProduct. Since table DimProductSubcategory does not have any column from DimProduct, it is not filtered by filter context. For the same reason, you can add any columns from DimProduct to the filter context and none of them would impact DimProductSubcategory.
Answer to question #2.
In the first formula
Calculate(CountRows(DimDate), FactSales)
Both table DimDate and table FactSales share columns from DimDate, so DimDate is filtered by FactSales.
In the second formula
Calculate(CountRows(DimDate), All(FactSales))
All(FactSales) blocks any columns from FactSales, but since the filter context is empty, it has no effect. When DimDate is evaluated, filter context is still empty.
In the third formula
Calculate(CountRows(DimDate), Filter(All(FactSales), true))
The All function is not at the top level of setfilter argument, table Filter(All(FactSales), true) is added to filter context, table DimDate is filtered by filter context for the same reason as in the first formula.


Tuesday, February 22, 2011

MDX Overwrite Semantics and Complex Attribute Relationship

The past month has been extremely busy for me so I didn’t get to write more blogs. Today we’ll resume the exploration of MDX calculation engine. In this post I am going to describe a common mistake made by people when writing MDX calculations that can be very hard to diagnose.

WARNING: The MDX overwrite behavior I am going to describe in this post applies to overwriting to a physical member or the [All] member. Overwriting to a calculated member has its own set of rules which are not covered here.
An Example
Let’s start with a simple example using Adventure Works DW 2008 database. First create a calculated measure, [m], that returns [Internet Sales Amount] for the first quarter of fiscal year 2004.
create member [Adventure Works].[Measures].[m] as
([Internet Sales Amount], [Date].[Fiscal].[Fiscal Quarter].[Q1 FY 2004])

Next send a query to check the value of [m].
select [m] on 0
from [Adventure Works]

m
$2,744,340.48


Now send another query calculating [m] but start with different calendar quarters.
select [m] on 0,
[Date].[Calendar].[Calendar Quarter].members on 1
from [Adventure Works]


m
Q3 CY 2001
(null)
Q4 CY 2001
(null)
Q1 CY 2002
(null)
Q2 CY 2002
(null)
Q3 CY 2002
(null)
Q4 CY 2002
(null)
Q1 CY 2003
(null)
Q2 CY 2003
(null)
Q3 CY 2003
$2,744,340.48
Q4 CY 2003
(null)
Q1 CY 2004
(null)
Q2 CY 2004
(null)
Q3 CY 2004
(null)
Q4 CY 2006
(null)


Why don’t we see the value, $2,744,340.48, in all cells? Didn’t the MDX formula of [m] change whatever calendar quarter to the first quarter of fiscal year 2004? The answer lies in MDX overwrite semantics and attribute relationship of the [Date] dimension.
Examine the Example Based on MDX Overwrite Rules
Before we delve into details, let’s establish some terminologies first. MDX attribute relationship defines functional dependency between two attributes, e.g.
[Calendar Quarter] [Calendar Semester] → [Calendar Year].
If A B, we say B is related to A and A is relating to B. Therefore, [Calendar Semester] and [Calendar Year] are related attributes of [Calendar Quarter], and reversely [Calendar Quarter] and [Calendar Semester] are relating attributes of [Calendar Year].  On the other hand, [Fiscal Week] and [Calendar Quarter] are not related to each other.
Every MDX expression is evaluated in a context. In a simple case, the context includes the current cell which is defined by the current coordinates of all attributes in the cube. When an MDX expression, like ([Internet Sales Amount], [Date].[Calendar Year].[CY 2004]), overwrites the coordinates of some attributes to non-All members, it also overwrites the coordinates of all related and relating attributes. The following diagram illustrates how MDX overwrite semantics work when you set non-All slices to some attributes.

The common mistake I referred to at the beginning of the post is when people forget about the slices left over at the unrelated attributes. When dimension autoexists is applied and the new slices set by the MDX expression do not exist with the slices left over on the unrelated attributes, you end up with cells that don’t exist. Note that we don’t have this problem when there is only a simple linear attribute relationship defined on the dimension.

In case of a single linear relationship, all attributes in the dimension are always overwritten, either explicitly or implicitly, when any attribute is set to a non-All member. The problem arises only when there is a complex attribute relationship, one with tree-like structure.
Going to back to the Adventure Works example, to calculate the value of any cell, an initial cell coordinate is set to a quarter from the [Calendar] hierarchy. Moreover, all related and relating attributes are set implicitly as well. See a simplified version of attribute relationship below. Every attribute in the diagram, except for [Month Name] is set to a slice that corresponds to a calendar quarter.

After applying the MDX expression associated with calculated measure [m], some attribute slices change to new ones, shown as colored boxes below, other attribute slices retain the previous values, shown as white boxes below.

You get a valid new cell only when the new slices correspond to the first quarter of fiscal year 2004 exist with the untouched old slices derived from the original calendar quarter; otherwise you get a cell that doesn’t exist hence a NULL value for the MDX formula. In this case only the third quarter of calendar year 2003 produces valid cell coordinates. To force setting the current coordinate to the first quarter of fiscal year 2004 regardless of the current calendar quarter, you have to explicitly overwrite all attributes related to the [Calendar] hierarchy like below:
create member [Adventure Works].[Measures].[m] as
(
      [Internet Sales Amount],
      [Date].[Fiscal].[Fiscal Quarter].[Q1 FY 2004],
      [Date].[Calendar].[All]
)

Official Rules
The above example is based on overwriting the current coordinate to a non-All member. But what about the other cases? Well, the following table lists all combinations of how overwriting one attribute can affect its related or relating attributes.
Assume A B.

Explicit Overwrite
Result
A.All to A.All
B unaffected
A.x to A.All
B to B.All
A to A.x
B to Exists(B.members, A.x)
B.All to B.All
A to A.All
B.x to B.All
A to A.All
B to B.x
A to A.All


An implicit overwrite is when an attribute is moved because of an overwrite on a relating or related attribute. When an attribute is impacted by both an explicit overwrite and an implicit overwrite, the explicit takes precedence. Implicit overwrites do not overwrite related or relating attributes.
Parent Child Dimension
According to the overwrite rules discussed so far, overwriting the key attribute of a dimension to a non-All member should overwrite all other attributes in the dimension implicitly. But this does not work for parent child dimensions.
If you run query
with member measures.x as
(
      [Measures].[Amount],
      [Account].[Account].[Work in Process]
)
select x on 0,
([Account].[Account].[Raw Materials], [Account].[Account Number].[1162]) on 1
from [Adventure Works]


x
Raw Materials
1162
(null)


You get back null result even though the calculation overwrites the key attribute [Account]. You have to explicitly overwrite [Account Number] attribute to get back the [Amount] for [Work in Process].
with member measures.x as
(
      [Measures].[Amount],
      [Account].[Account].[Work in Process],
      [Account].[Account Number].[All]
)
select x on 0,
([Account].[Account].[Raw Materials], [Account].[Account Number].[1162]) on 1
from [Adventure Works]


x
Raw Materials
1162
$1,393,582.00


The official rule here is that:
Overwriting key attribute of parent child hierarchy does not overwrite other attributes except that of its parent.
Complex Relationships Are Very Common
Unless you define a single linear relationship for a dimension, you will end up with a complex relationship. Specifically, when there are more than two attributes in a dimension and you didn’t define any relationship, the default one is a tree-like relationship.
MDX Writeback with Custom Weight Expression
Users are likely to make the mistake we have discussed so far when the current cell coordinates contain many slices on numerous attributes. This is particularly true when it comes to MDX writeback with custom weight expression. When an MDX UPDATE CUBE statement is sent to Analysis Services, the desired result is allocated to leaf level nodes. So if you are writing a custom weight formula, the current context is always a leaf level cell with a slice on every regular attribute. If you are not careful overwriting all attributes in a dimension, your weight expression is likely to return NULL values and you won’t get the allocation you desired.
Conclusion
The complex rules of MDX overwrite semantics combined with a tree-like attribute relationship can easily lead to some very frustrating bugs in your MDX formula. You must make sure to overwrite slices on all attributes you don’t want to keep and preserve the slices on all attributes you do want to keep. Remember that the rules are different for parent child dimensions. If you have a simple tuple like MDX formula that returns unexpected NULLs, you should check whether you have violated the guidelines given in this blog post.